Overview
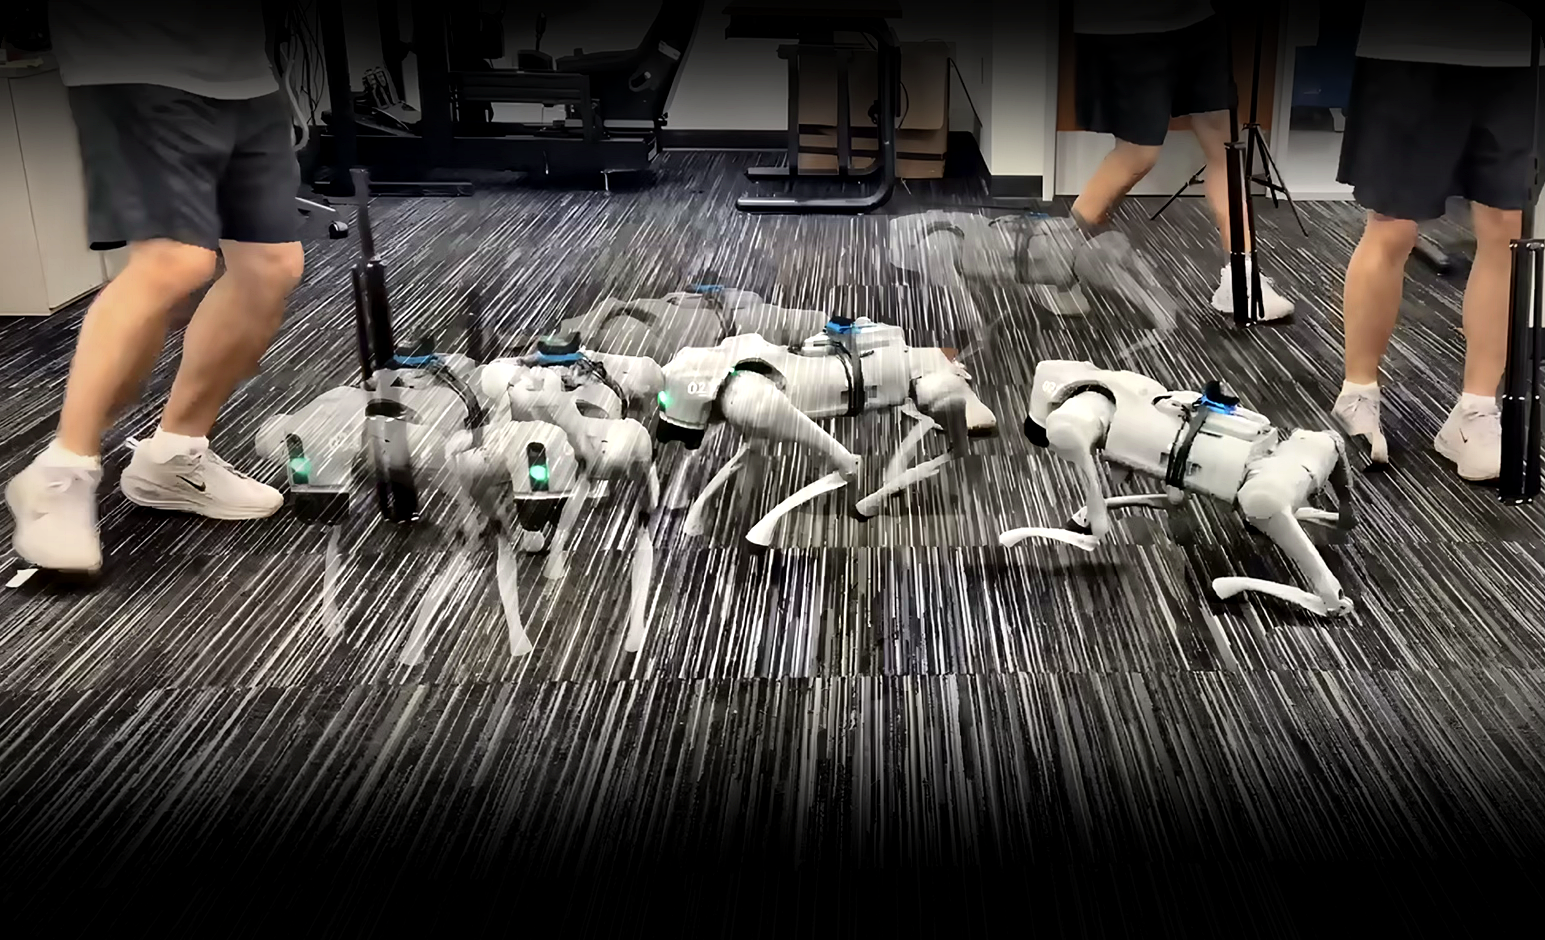
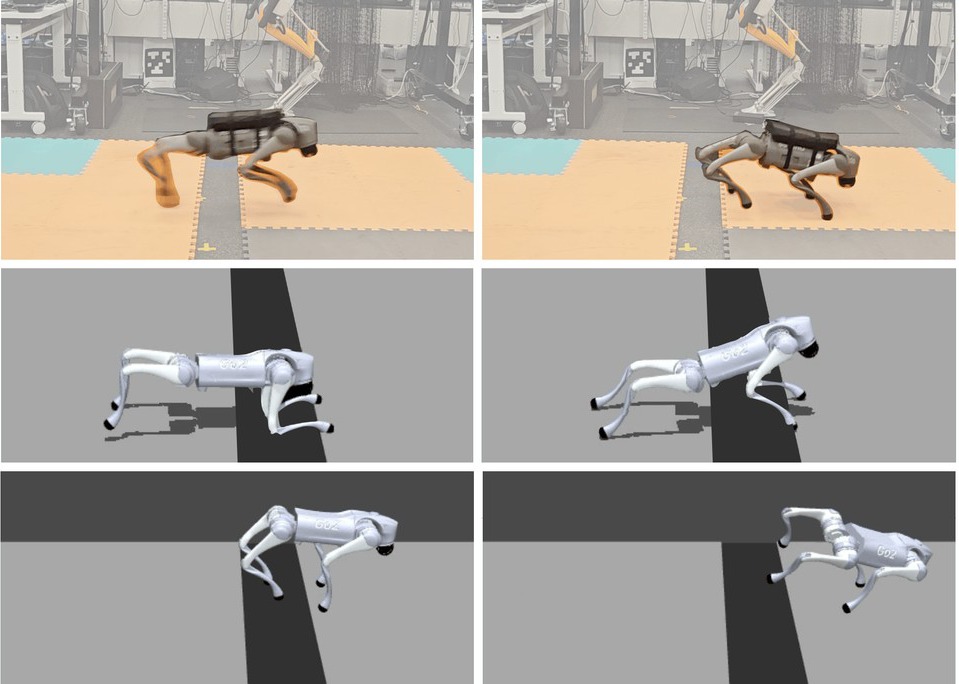
We propose a framework for training competitive robots that maintain safety without sacrificing performance, by separating safety synthesis from task learning in a two-stage reinforcement learning process. We formulate interactions as safety-critical games, prove that safety filtering preserves non-exploitability when players maintain safe maneuvers, and demonstrate superior performance over existing safe RL methods in quadruped touchdown games and hardware tests.
Contributors
Ruihan Wu, Rui Yang, Donggeon David Oh, Duy Nguyen, and Haimin Hu